Under Development: Title Block OCR and Structuring
Reading drawing title blocks accurately and turning them into a database.
Cell-by-cell text recognition of title blocks is difficult to do accurately even with the latest AI models. We structure the results with our own pipeline and register them in a database that can be searched and used.
Title Blocks Are Difficult to Read
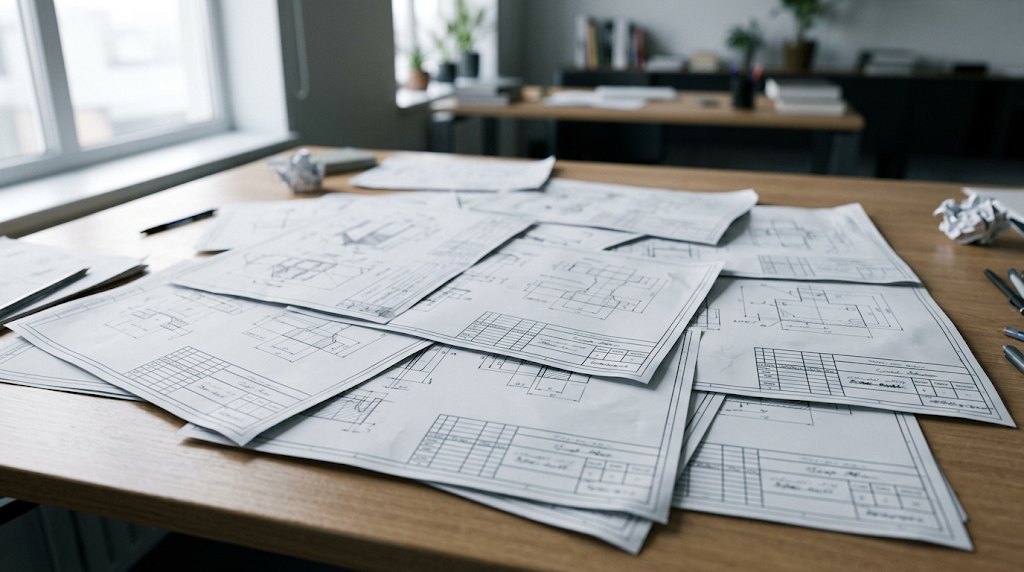
The graphical part of a drawing is created in accordance with standards. By contrast, the items and layout of the title block differ from company to company.
Cells are small, handwritten-style entries and approval or round seals are present, and scanned images are degraded. A title block with these conditions is a target for which even general-purpose OCR and the latest AI models have difficulty achieving accuracy as they are.
Usage Overview
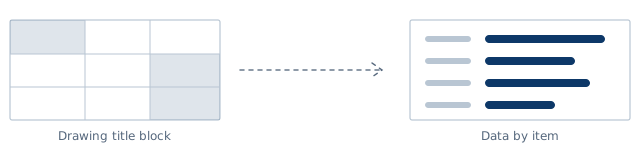
Our aim is that, once a drawing is imported, the contents of its title block are organized as data by item and can be searched and used.
- Import the drawingPrepare a PDF or a scanned drawing.
- The title block contents become data by itemItems such as name, drawing number, and creation date are organized individually.
- Search and use the dataThe data is registered in a database and can be used to search and manage drawings.
Intended Scope
- Text
Japanese and English are assumed.
- Drawings
PDF and scanned drawings are assumed.
- Title Block Format
We aim to handle the item structures and layouts that differ from company to company as they are.
Development Status
The software is currently under development, and we are verifying recognition accuracy using drawings in a variety of formats. Figures such as accuracy will be presented, together with their basis, once they have been confirmed.
For those facing challenges
in digitizing drawing title blocks.
Our Representative will personally explain the features under development. Please tell us about your current challenges and how you manage your drawings.
Contact Us